I Took WordPress Off the Internet: Karl.Fail on Astro and Cloudflare Pages
How I moved Karl.Fail to Astro and Cloudflare Pages, kept WordPress private, and built automatic publishing, local search and a faster reading…
In this story
I have already written an entire post about locking down my WordPress setup. Cloudflare WAF rules, firewall restrictions, blocking XML-RPC, watching scanners poke at things. The whole “we have SIEM at home, son!” situation.
So, naturally, my next improvement was to stop letting the internet talk to WordPress at all. 😂
I still like the editor. My posts are there, my images are there, and I do not particularly feel like moving years of content into Markdown just because I have developed another infrastructure opinion. I wanted to keep writing in WordPress while getting its PHP, plugins, login page and REST API out of the public request path.
I also wanted the blog to feel better to read. Something closer to Medium: proper typography, a comfortable article width, decent code blocks and a mobile page that does not need a small motivational speech before it loads. Blog and Projects should stay separate. Search should work. Old links should keep working. And yes, I wanted those mobile Lighthouse scores to say 100. I am apparently very susceptible to four green circles (🟢🟢🟢🟢 – Nice, ain’t it?).
The result is WordPress behind the scenes, Astro for the frontend, and Cloudflare Pages delivering the files. WordPress still has a job. I have just considerably reduced its public-facing responsibilities.
I know I know the idea isn’t new, it doesn’t have to be. Lots of people use WordPress as headless CMS nowadays.
What I Actually Changed
Here is the before-and-after version before I get distracted by image processing:
| Before | Now | |
|---|---|---|
| Public requests | Reached my WordPress origin through Cloudflare | End at Cloudflare Pages |
| Page rendering | WordPress, PHP and the database | HTML generated during the build |
| Writing | WordPress | Still WordPress |
| Search | Needed a frontend implementation | Pagefind, using static files in the browser |
| Images | Historical WordPress uploads and URLs | Locally generated responsive WebP files |
| Publishing | WordPress served the change directly | A local job builds, checks and uploads the site |
The important part for my home network is where the public request stops. Someone reading about my latest questionable homelab decision no longer needs a connection to a PHP application running inside it OR my home, you can keep your shoes on now muchacho.
Reader -> Cloudflare Pages -> static website

Inside the private network:
WordPress -> import -> Astro -> Pagefind -> checks -> outbound upload
I still have to trust and maintain the editor and the builder. If somebody compromises either of those, they could try to publish malicious files. The deployment token also deserves actual protection. What I have removed is the public WordPress application path, which was the thing I wanted to get rid of in the first place.
Honestly that vector is just simply not feasible… I ain’t got no worries.
Phase 1: Keep the Editor, Lose the Public WordPress
I did not need another container for this. The builder runs in the existing WordPress LXC, under its own Unix account. WordPress stores the content; Node imports it, Astro builds it, and Wrangler pushes the result out to Cloudflare.
That account gets the permissions it needs for generated content and build output. The Cloudflare token stays outside the source tree and outside PHP’s environment. Two Unix users in one LXC are still sharing a container, so I would not use this arrangement to isolate applications I actively distrust. For my own editor and publishing job, it keeps the setup manageable.
The WordPress origin is reachable through the private network or (my personal) VPN. The public domain points at Pages, and the old public origin route is closed. This last part is easy to miss: changing DNS does not stop somebody who already knows your old origin address. Check the reverse proxy, tunnel, firewall and the origin itself.
I also went through the plugins. A public page-cache plugin is not doing much for me when WordPress no longer serves the public page. The same applies to frontend features now handled by Astro. I kept what the editor still uses and removed the retired pieces after checking their dependencies.
If you copy this, check what your plugins actually contribute before deleting them. An innocent-looking shortcode can be half an article, and removing a code-block plugin can also remove the language metadata you wanted to preserve. Keep one minimal active theme for WordPress’s editor and preview behavior. Nobody visiting the static site receives it.
Phase 2: Build the Blog Before Anyone Asks for It
Astro generates the HTML in advance. I do not need a public Node server, Pages Functions or a Cloudflare runtime adapter for this site. The browser gets the finished document and a few small scripts for search, appearance and copying code.
The importer reads published posts and pages through the private WordPress REST API. Drafts and password-protected posts stay out. It also reads categories, tags, featured attachments and the SEO fields used by the production site. Existing article paths survive the migration, and Blog and Projects keep their separate archives.
There is a bit more work here than fetching content.rendered and hoping for the best. WordPress HTML can contain plugin markup, old upload URLs and embeds that expect somebody else’s JavaScript. I sanitize it, turn approved media into local assets, and generate the parts the public frontend needs.
For SEO, that means preserving titles, descriptions, canonical URLs and indexing decisions, then generating the sitemap, RSS feed and structured data from the exported content. Rank Math can remain useful as an editor for those fields. Its presence in WordPress does not automatically put them into an Astro page; you have to export and render them.
One thing I was quite stubborn about: I was not going to break old links because I wanted a faster blog. Make an inventory of your existing URLs before you start. If a path really has to change, give it an explicit redirect.
Phase 3: Yes, Saving a Post Starts a Build
I wanted to keep the normal WordPress workflow. Write something, fix the inevitable typo, press Publish. I do not want publishing a blog post to come with a second job in a terminal.
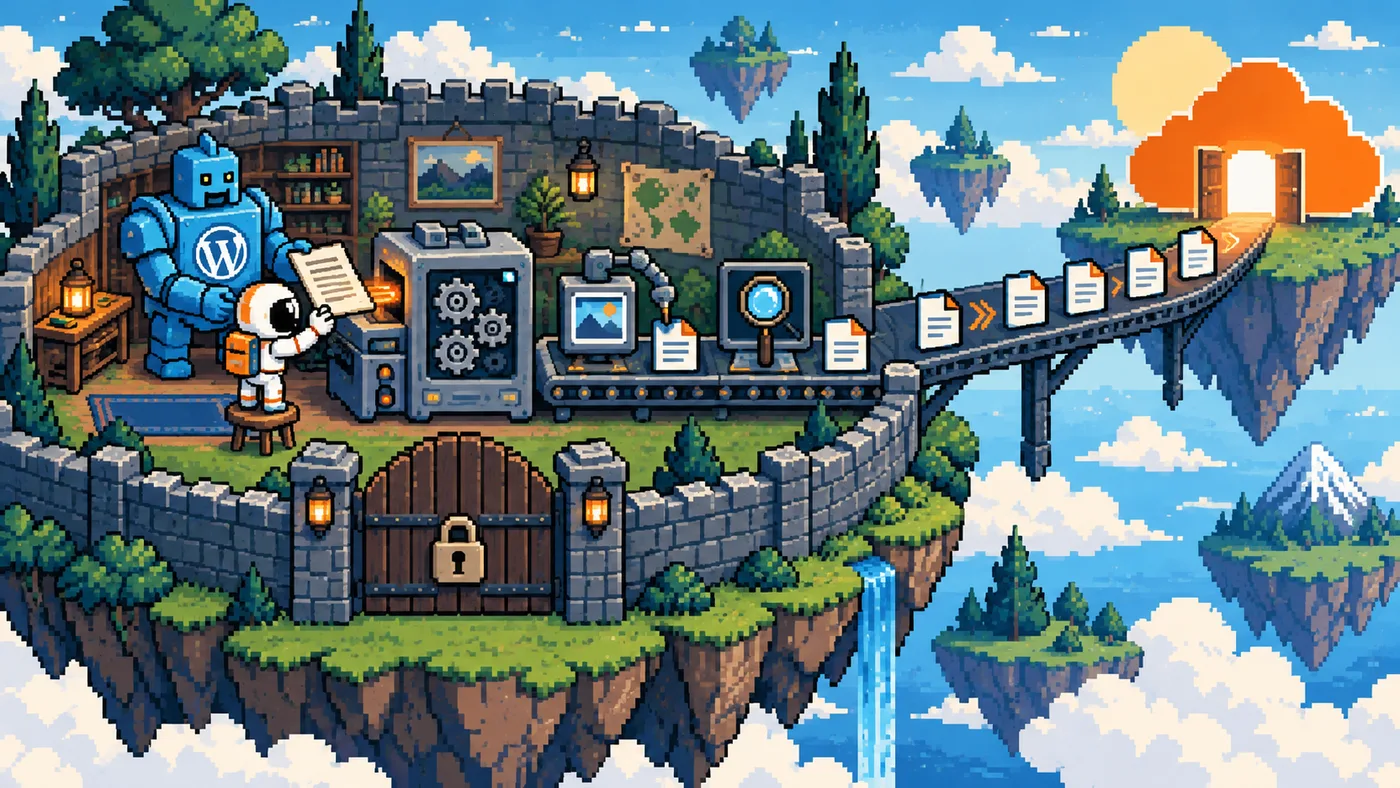
The implementation uses a small WordPress must-use plugin and a systemd timer. The plugin changes a revision marker when published content or related data changes. The timer checks that marker about once a minute. An unchanged marker is a quick exit; a changed marker starts the publishing job.
There is no public webhook waiting for somebody to poke it. The check and build happen locally, and the upload is outbound.
The job does this:
Read the revision and compare it with the last successful upload
Import published content and download the required media
Check that WordPress did not change during the import
Build the static pages and Pagefind index
Validate the output
Upload dist/ to Cloudflare Pages
Record the successful revision
If an image is missing or the build fails, it stops before uploading. If the upload fails, it does not mark the revision as deployed. The next timer run can try again, and readers keep getting the previous deployment.
A lock prevents two jobs from trying to build in the same directory. The timer waits until the service has finished before starting its next interval. I also have a daily reconciliation build for changes the normal signal might miss.
This means a published change takes the timer delay plus build and upload time to appear. For my blog, that is fine. I can live with a short delay before the internet receives the corrected spelling of “permissions.”
Scheduled posts still need WordPress cron. Moving the editor off the public internet can remove the visits that used to trigger it, so run scheduled jobs deliberately rather than waiting for a visitor who can no longer reach WordPress.
Cloudflare only receives the finished dist/ directory through Pages Direct Upload. It never needs to log into my editor. My source repository is a backup of the code and lockfile, not a database export or an invitation for a remote CI runner into my network.
The Images Were Staying. All of Them.
I was not willing to call the migration done and quietly remove whichever images were inconvenient. If an old URL is broken, that does not necessarily mean the picture is gone. Check the uploads directory and attachment metadata before writing it off.
Featured images deserve special attention. WordPress stores them separately from the article body, so walking through <img> tags alone will miss your covers. The importer needs attachment metadata as well as the body HTML. It also needs to recognize when a cover is already inside the article, unless showing the same creature twice is an intentional design choice.
I use Sharp to generate responsive WebP files before Astro builds the pages. That ordering matters because Astro copies the public assets during its build. Generating pictures halfway through page rendering is a good way to end up with correct-looking HTML and files that never made it into the deployment.
The production pipeline uses several widths, caps them at the original image size, applies orientation and removes source metadata. Each output filename contains a hash of the actual encoded bytes. The page gets srcset, sizes and explicit dimensions, so a phone can request a suitable image without reserving a surprise amount of space halfway through the article.
Astro has its own image tooling. I used an explicit import pipeline because I already had years of WordPress HTML and attachment references to deal with.
For the audit, I wanted images to actually decode. An HTTP 200 is reassuring until you discover that your “image” is an HTML error page. Check covers, body images and every generated size, then check the live site too.
Code Blocks Are Part of the Article
Most of what I write contains commands, configuration files or code. If the migration makes those harder to read or changes what gets copied, I have made the blog worse while congratulating myself on its performance.
Shiki highlights the code during the build and provides light and dark colors. Language metadata comes from the editor where available; otherwise, the block stays plain text. I do not need a browser-side highlighter confidently deciding that a firewall configuration is JavaScript.
The copy button copies the code itself, including indentation. After a successful copy it shows a checkmark and a short confirmation. Small thing, but I want to know whether clicking the button did anything before pasting a command into a server.
The same goes for the theme switch. On the first visit, the page follows the device preference. If you choose light or dark, that choice is saved in localStorage and used on the next load. There is no extra “Auto” button taking up space next to the moon.
Check code after it reaches the CDN, too. Email-address obfuscation can rewrite addresses inside examples even when the local build is perfect. A command containing [email protected] is not improved by having excellent syntax colors.
Search, Without Another Thing to Host
I have used Pagefind before, and I wanted it here too. I already host enough things. The blog did not need to become the reason I maintain a search cluster.
Pagefind reads the generated HTML after Astro finishes and produces a static search index. The browser loads the engine and the index pieces it needs from the same site. WordPress can be offline and search still works.
I use the Pagefind API with a small UI that matches the rest of the blog. Articles are marked for indexing, while archives, policy pages and the search page stay out. The search field is deliberately plain; I wanted people to find a post, not operate a dashboard.
Queries go into the URL fragment, such as /search/#proxmox, and the application does not save them in localStorage. The browser does not send that fragment in the HTTP request. Cloudflare still sees the requests needed to deliver the site and search assets, so I am not pretending that “static” makes a CDN disappear from the privacy policy.
Pagefind also uses WebAssembly. If you run a strict Content Security Policy, account for that with the appropriate Wasm permission. Do not respond to a broken search box by casually enabling every form of unsafe-eval.
The Folder We Upload Should Be Extremely Boring
I was quite specific about this during the migration: no secrets, no weird files, no accidentally uploaded backup of half my infrastructure.
Wrangler gets dist/. It does not get the project root, WordPress, a database dump or an environment file. The output checker uses an allowlist for expected routes and assets, rejects symlinks and unexpected files, and scans for secret formats and known sensitive values. Compressed Pagefind data has to be decoded before checking it as well.
The repository has its own ignore rules and source checks. A private repository is useful, but “it is private” is a fairly weak argument for committing a live token to it.
I still review what the site loads in a browser. External fonts, embeds and scripts do not become desirable just because they survived the importer. The frontend uses system fonts and serves its own assets. Its notice explains the storage it actually uses and possible Cloudflare security cookies; it does not pretend that dismissing a box is consent to an analytics service I have not installed.
About Those Green Circles
The representative mobile Lighthouse checks on the production blog reached:
| Category | Score |
|---|---|
| Performance | 100 |
| Accessibility | 100 |
| Best Practices | 100 |
| SEO | 100 |
Yes, I am pleased with that. 💅
I also care whether the article is readable on an actual narrow screen. We checked mobile and desktop widths, both color modes, image loading, horizontal overflow, search, clipboard contents and the stored appearance choice. A perfect score does not excuse a code block that you cannot read in dark mode.
These are results from the pages and conditions we tested. I did not collect a controlled before-and-after WordPress benchmark, and I have not tested every article on every phone. The search results page is deliberately noindex, so its crawlability warning is expected.
WordPress MCP Still Fits In
Keeping WordPress as the editor also means I can use its official MCP Adapter for editorial access. It bridges WordPress abilities to an MCP client, which can discover the operations available to it and read their input schemas.
For writing, I want a client to fetch an article and save a draft through a dedicated account with the appropriate permissions. When editing an existing draft, it should check the latest modification timestamp. Silently overwriting somebody’s changes is annoying enough when I do it myself.
The adapter provides the connection and discovery layer. You still need reviewed abilities that enforce permissions on the WordPress side. Our draft-saving operation refuses to alter published posts, and publishing remains a separate action. Keep the endpoint private and use a revocable Application Password rather than handing a client your main Administrator login.
Once a post is published, the ordinary revision check picks it up. MCP is another way to work with the editor; the same build process publishes the website.
If You Want to Do This to Your Own Blog
Start with a backup of the database, uploads and redirect configuration, and make sure you can restore it. Then inventory your URLs and content features before building anything. A blog containing ordinary articles is a much easier migration than a site whose “article” is actually three shortcodes, a form and a checkout.
I have included a small reference implementation below. It has the files needed to import ordinary posts and pages, optimize still images, render the site, build search and run the publishing job. The instructions also cover the private editor, credentials, first deployment and cutover.
It is a starting point you can inspect and adapt. The production blog has additional archive handling, SEO integration, image alias repair and output policy. The reference calls out those differences instead of claiming to reproduce every WordPress plugin you might have installed.
Before changing DNS, compare your source and output, test the built site, and check the deployment on its temporary hostname. Test edits, unpublishing and deletion as well as adding a shiny new article. After cutover, verify that the old WordPress origin is actually closed from outside your network. Keep a previous static deployment available so a rollback does not require making WordPress public again.
I still get to use the editor I know, and readers get a much lighter page. Better yet, shutting down the editor does not shut down the blog. For somebody who keeps finding new things to do to his homelab, I appreciate that arrangement.
Sleep tight now, and may your next WordPress update only affect the part of the website nobody is visiting. ❤️
The Files, If You Are Following Along
Open the reference implementation and deployment steps
Prerequisites and boundaries
Use a Linux build machine with systemd, Node.js supported by the pinned Astro release, npm and a private HTTPS WordPress origin. Trust its certificate on the build host. Do not disable TLS verification. The builder can live beside WordPress, with a separate Unix account and permissions that keep PHP away from the publishing credentials.
The example supports published posts and pages with unique, pretty permalinks ending in /. It rejects reserved routes and unusual paths for explicit mapping. It does not generate taxonomy archives or custom post types automatically. Export those and add their routes if your URL inventory requires them. Map a WordPress page used as the homepage deliberately; do not drop its content.
Rendered plugin content still needs review. Active embeds and unsupported markup are removed. Still images are supported; animations, downloads, forms and other interactive features need an explicit migration decision. Repair historical image URLs against verified uploads or attachment metadata before cutover.
Create a dedicated WordPress Subscriber with an Application Password for reading published content and the authenticated revision marker. Editorial writing should use a separate account. All domains and credentials below are placeholders.
Project and environment
Create an empty project directory:
mkdir wordpress-static
cd wordpress-static
mkdir -p src/lib src/layouts src/pages scripts public .statepackage.json:
{
  "private": true,
  "type": "module",
  "scripts": {
    "build": "node scripts/import.mjs && astro build && pagefind --site dist --root-selector '[data-pagefind-body]' && node scripts/verify.mjs",
    "preview": "astro preview --host 127.0.0.1"
  },
  "dependencies": { "astro": "7.3.8", "cheerio": "1.2.0", "sanitize-html": "2.18.1", "sharp": "0.35.5", "shiki": "4.5.0" },
  "devDependencies": { "pagefind": "1.5.2", "wrangler": "4.151.0" }
}
Save package.json, then run npm install. Commit package-lock.json and use npm ci for subsequent installations. Review dependency updates before changing pinned versions. The code follows Astro’s headless WordPress integration and adds an import pass for sanitization and local assets.
astro.config.mjs:
import { defineConfig } from 'astro/config';
export default defineConfig({ site: process.env.SITE_URL, output: 'static', trailingSlash: 'always' });.gitignore:
node_modules/
dist/
.astro/
.wrangler/
.state/
public/media/
.env*
*.log
Create /etc/wordpress-static.env outside the project. Set its owner to root and mode to 0600, then supply your actual values:
WP_URL=https://wordpress.internal.example
WP_USER=static-reader
WP_PASSWORD=YOUR_WORDPRESS_APPLICATION_PASSWORD
SITE_URL=https://blog.example.com
MEDIA_ORIGINS=https://wordpress.internal.example,https://blog.example.com
CLOUDFLARE_ACCOUNT_ID=YOUR_ACCOUNT_ID
CLOUDFLARE_API_TOKEN=YOUR_SCOPED_PAGES_TOKEN
CF_PROJECT=my-static-blog
WRANGLER_SEND_METRICS=false
MEDIA_ORIGINS is an exact comma-separated allowlist with no spaces. Old public upload URLs must still resolve during the import, or be mapped to a verified private upload location. Adding the public static origin to an allowlist will not recreate its old uploads after DNS changes.
Credentials are read only by server-side build code. Do not use Astro’s PUBLIC_* prefix for them. systemd reads the root-owned file before dropping privileges to the build account.
Import before building
The library paginates REST results, excludes protected content, sanitizes HTML and generates responsive WebP files. Source downloads are limited to 25 MiB and 80 million decoded pixels. Unknown code languages stay plain text. Featured images use embedded attachment metadata.
This reference rebuilds media each time. Add a verified source-to-derivative cache if that becomes too slow for your library.
src/lib/wp.mjs:
import sanitize from 'sanitize-html';
import * as cheerio from 'cheerio';
import sharp from 'sharp';
import { codeToHtml, bundledLanguages } from 'shiki';
import { mkdir, writeFile, readFile } from 'node:fs/promises';
import { createHash } from 'node:crypto';

const cms = new URL(process.env.WP_URL);
const site = new URL(process.env.SITE_URL);
if (cms.protocol !== 'https:') throw Error('WP_URL must use trusted HTTPS');
const mediaOrigins = new Set((process.env.MEDIA_ORIGINS || cms.origin).split(','));
const credentials = Buffer.from(`${process.env.WP_USER}:${process.env.WP_PASSWORD}`).toString('base64');
export const text = html => cheerio.load(html || '').text();
const cache = new Map();
async function request(url, authenticated = false) {
  const response = await fetch(url, {
    redirect: 'error', signal: AbortSignal.timeout(30000),
    headers: authenticated ? { Authorization: `Basic ${credentials}` } : {}
  });
  if (!response.ok) throw Error(`HTTP ${response.status}: ${new URL(url).pathname}`);
  return response;
}
async function list(type) {
  const result = [];
  for (let page = 1, pages = 1; page <= pages; page++) {
    const url = new URL(`wp-json/wp/v2/${type}`, cms.href.replace(/\/?$/, '/'));
    url.search = new URLSearchParams({ per_page: '100', page: String(page), status: 'publish', _embed: '1' });
    const response = await request(url, true);
    pages = Number(response.headers.get('x-wp-totalpages') || 1);
    result.push(...await response.json());
  }
  return result.filter(post => !post.content.protected);
}
async function image(source) {
  const url = new URL(source, cms);
  if (!mediaOrigins.has(url.origin) || !url.pathname.includes('/wp-content/uploads/')) {
    throw Error(`Unapproved image origin/path: ${url.origin}`);
  }
  if (cache.has(url.href)) return cache.get(url.href);
  const response = await request(url);
  const chunks = []; let length = 0;
  for await (const chunk of response.body) {
    length += chunk.length;
    if (length > 25 * 1024 * 1024) throw Error('Image exceeds 25 MiB');
    chunks.push(chunk);
  }
  const buffer = Buffer.concat(chunks);
  const metadata = await sharp(buffer, { limitInputPixels: 80000000 }).metadata();
  // ponytail: still images only; handle animation/video explicitly before migration.
  if (metadata.pages > 1) throw Error('Animated image needs an explicit migration decision');
  const variants = [];
  await mkdir('public/media', { recursive: true });
  for (const width of [360, 680, 960, 1400]) {
    const { data, info } = await sharp(buffer, { limitInputPixels: 80000000 })
      .rotate().resize({ width, withoutEnlargement: true }).webp({ quality: 82 })
      .toBuffer({ resolveWithObject: true });
    const name = createHash('sha256').update(data).digest('hex') + '.webp';
    await writeFile(`public/media/${name}`, data);
    if (!variants.some(v => v.width === info.width)) {
      variants.push({ src: `/media/${name}`, width: info.width, height: info.height });
    }
  }
  const largest = variants.at(-1);
  const result = { ...largest, srcset: variants.map(v => `${v.src} ${v.width}w`).join(', ') };
  cache.set(url.href, result);
  return result;
}
async function prepare(post, type) {
  const original = new URL(post.link);
  if (original.search || !original.pathname.endsWith('/')) throw Error('Map non-pretty permalinks first');
  const pathname = decodeURI(original.pathname);
  if (!/^\/(?:[\p{L}\p{N}_~-]+\/)*$/u.test(pathname)) throw Error('Review unusual permalink');
  const allowed = [...new Set([...sanitize.defaults.allowedTags, 'img', 'figure', 'figcaption', 'h1', 'h2'])];
  const $ = cheerio.load(sanitize(post.content.rendered, {
    allowedTags: allowed,
    allowedAttributes: { a: ['href', 'title'], img: ['src', 'alt'], code: ['class'], pre: ['class'] }
  }), null, false);
  for (const element of $('img').toArray()) {
    const node = $(element);
    node.attr({ ...await image(node.attr('src')), sizes: '(max-width: 720px) 100vw, 680px', loading: 'lazy', decoding: 'async' });
  }
  for (const element of $('a[href]').toArray()) {
    const node = $(element); const url = new URL(node.attr('href'), original);
    if ([cms.origin, site.origin, original.origin].includes(url.origin)) node.attr('href', url.pathname + url.search + url.hash);
  }
  for (const element of $('pre').toArray()) {
    const node = $(element), code = node.find('code');
    const language = ((code.attr('class') || node.attr('class') || '').match(/language-([\w+-]+)/) || [])[1];
    node.replaceWith(await codeToHtml(code.length ? code.text() : node.text(), {
      lang: language in bundledLanguages ? language : 'text',
      themes: { light: 'github-light', dark: 'github-dark' }
    }));
  }
  const featured = post._embedded?.['wp:featuredmedia']?.[0];
  return {
    id: post.id, type, path: pathname, title: text(post.title.rendered),
    description: text(post.excerpt.rendered).trim().slice(0, 160),
    date: post.date_gmt + 'Z', modified: post.modified_gmt + 'Z',
    html: $.html(), cover: featured?.source_url ? await image(featured.source_url) : null
  };
}
let pending;
export function importPosts() {
  return pending ||= (async () => {
    const result = [];
    for (const type of ['posts', 'pages']) {
      for (const post of await list(type)) result.push(await prepare(post, type));
    }
    if (new Set(result.map(p => p.path)).size !== result.length) throw Error('Duplicate permalinks');
    if (result.some(p => ['/', '/search/', '/404/'].includes(p.path))) throw Error('Map reserved routes first');
    return result;
  })();
}

export async function posts() { return JSON.parse(await readFile('.state/content.json', 'utf8')); }scripts/import.mjs:
import { mkdir, writeFile, rm } from 'node:fs/promises';
import { importPosts } from '../src/lib/wp.mjs';
await mkdir('.state', { recursive: true });
await rm('public/media', { recursive: true, force: true });
await writeFile('.state/content.json', JSON.stringify(await importPosts()), { mode: 0o600 });
Layout and routes
The layout supplies native typography, OS-default appearance, a stored light/dark override and a copy button. The catch-all route preserves the original permalink path.
The cover is rendered separately in this small example. Add attachment-identity deduplication if your covers are also present in article bodies. The excerpt supplies a fallback description; it does not replace your existing SEO metadata. Export and render plugin titles, descriptions, canonical overrides, noindex rules and article structured data before migrating a site that uses them.
src/layouts/Base.astro:
---
const { title, description = '', noindex = false, image } = Astro.props;
const canonical = new URL(Astro.url.pathname, Astro.site);
---
<!doctype html>
<html lang="en">
<head>
  <meta charset="UTF-8" />
  <meta name="viewport" content="width=device-width, initial-scale=1" />
  <title>{title}</title>
  <meta name="description" content={description} />
  <link rel="canonical" href={canonical} />
  <meta property="og:title" content={title} />
  <meta property="og:description" content={description} />
  <meta property="og:url" content={canonical} />
  {image && <meta property="og:image" content={new URL(image, Astro.site)} />}
  {noindex && <meta name="robots" content="noindex,follow" />}
  <script is:inline>
    try {
      const choice = localStorage.getItem('theme');
      if (choice === 'light' || choice === 'dark') document.documentElement.dataset.theme = choice;
    } catch {}
  </script>
</head>
<body>
  <header><a href="/">Blog</a><a href="/search/">Search</a><button id="theme" aria-label="Switch color theme">◐</button></header>
  <main><slot /></main>
  <script>
    document.querySelector('#theme')?.addEventListener('click', () => {
      const root = document.documentElement;
      const dark = root.dataset.theme ? root.dataset.theme === 'dark' : matchMedia('(prefers-color-scheme: dark)').matches;
      root.dataset.theme = dark ? 'light' : 'dark';
      try { localStorage.setItem('theme', root.dataset.theme); } catch {}
    });
    document.querySelectorAll('pre').forEach(pre => {
      const code = pre.querySelector('code');
      if (!code) return;
      const button = document.createElement('button');
      button.textContent = 'Copy'; button.dataset.pagefindIgnore = ''; button.setAttribute('aria-label', 'Copy code');
      const status = document.createElement('span'); status.setAttribute('role', 'status'); status.dataset.pagefindIgnore = '';
      button.addEventListener('click', async () => {
        try { await navigator.clipboard.writeText(code.textContent || ''); button.textContent = '✓'; status.textContent = 'Copied'; }
        catch { status.textContent = 'Copy failed; select the code manually'; }
        setTimeout(() => { button.textContent = 'Copy'; status.textContent = ''; }, 2000);
      });
      pre.before(button, status);
    });
  </script>
</body>
</html>
<style is:global>
  :root { color-scheme: light dark; --paper: #fff; --ink: #202020; }
  @media (prefers-color-scheme: dark) { :root:not([data-theme="light"]) { --paper: #181818; --ink: #eee; } }
  :root[data-theme="dark"] { color-scheme: dark; --paper: #181818; --ink: #eee; }
  :root[data-theme="light"] { color-scheme: light; }
  body { margin: 0; background: var(--paper); color: var(--ink); font: 18px/1.75 Georgia, serif; overflow-wrap: anywhere; }
  header, main { max-width: 680px; margin: auto; padding: 1.25rem; }
  header { display: flex; gap: 1.5rem; align-items: center; font-family: system-ui, sans-serif; }
  h1,h2,h3,button { font-family: system-ui, sans-serif; line-height: 1.25; }
  a { color: inherit; } img { max-width: 100%; height: auto; }
  pre { overflow: auto; padding: 1rem; font-size: .85rem; } table { display: block; overflow: auto; }
  button { min-height: 44px; cursor: pointer; } input { max-width: 100%; font: inherit; }
  @media (prefers-color-scheme: dark) {
    :root:not([data-theme="light"]) .shiki, :root:not([data-theme="light"]) .shiki span { color: var(--shiki-dark) !important; background-color: var(--shiki-dark-bg) !important; }
  }
  :root[data-theme="dark"] .shiki, :root[data-theme="dark"] .shiki span { color: var(--shiki-dark) !important; background-color: var(--shiki-dark-bg) !important; }
</style>src/pages/[...path].astro:
---
import { posts } from '../lib/wp.mjs';
import Base from '../layouts/Base.astro';
export async function getStaticPaths() {
  return (await posts()).map(post => ({ params: { path: post.path.slice(1, -1) }, props: { post } }));
}
const { post } = Astro.props;
---
<Base title={post.title} description={post.description} image={post.cover?.src}>
  <article data-pagefind-body={post.type === 'posts' ? '' : undefined}>
    <h1 data-pagefind-meta="title">{post.title}</h1>
    <time datetime={post.date}>{post.date.slice(0, 10)}</time>
    {post.cover && <img src={post.cover.src} srcset={post.cover.srcset} width={post.cover.width} height={post.cover.height} sizes="(max-width: 720px) 100vw, 680px" alt="" fetchpriority="high" />}
    <div set:html={post.html} />
  </article>
</Base>src/pages/index.astro:
---
import { posts } from '../lib/wp.mjs';
import Base from '../layouts/Base.astro';
const articles = (await posts()).filter(post => post.type === 'posts');
---
<Base title="My blog" description="Articles and projects">
  <h1>Blog</h1>
  {articles.map(post => <article><h2><a href={post.path}>{post.title}</a></h2><p>{post.description}</p></article>)}
</Base>src/pages/404.astro:
---
import Base from '../layouts/Base.astro';
---
<Base title="Page not found" noindex><h1>Page not found</h1><a href="/">Back to the blog</a></Base>
For separate Blog and Projects archives, export categories, group posts by the relevant category IDs, and create the corresponding archive and pagination routes. Preserve any existing URLs from the inventory. The basic homepage above lists posts without generating those additional archives.
Sitemap, feed and response headers
Change the feed title and description and the sitemap domain in robots.txt. Preserve old feed GUIDs where subscriber continuity requires it; this reference uses canonical URLs as GUIDs. Add redirects from the URL inventory to _redirects and check for collisions with generated paths.
src/pages/sitemap.xml.js:
import { posts } from '../lib/wp.mjs';
export async function GET({ site }) {
const escape = value => String(value).replaceAll('&', '&').replaceAll('<', '<').replaceAll('"', '"');
const entries = ['/', ...(await posts()).map(post => post.path)];
return new Response('<?xml version="1.0" encoding="UTF-8"?><urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">' + entries.map(path => `<url><loc>${escape(new URL(path, site))}</loc></url>`).join('') + '</urlset>', { headers: { 'Content-Type': 'application/xml' } });
}src/pages/feed.xml.js:
import { posts } from '../lib/wp.mjs';
export async function GET({ site }) {
const escape = value => String(value).replaceAll('&', '&').replaceAll('<', '<').replaceAll('>', '>');
const articles = (await posts()).filter(post => post.type === 'posts');
const items = articles.map(post => `<item><title>${escape(post.title)}</title><link>${escape(new URL(post.path, site))}</link><guid isPermaLink="true">${escape(new URL(post.path, site))}</guid><pubDate>${new Date(post.date).toUTCString()}</pubDate><description>${escape(post.description)}</description></item>`).join('');
return new Response(`<?xml version="1.0" encoding="UTF-8"?><rss version="2.0"><channel><title>My blog</title><link>${escape(site)}</link><description>Latest articles</description>${items}</channel></rss>`, { headers: { 'Content-Type': 'application/xml' } });
}public/robots.txt:
User-agent: *
Allow: /
Sitemap: https://blog.example.com/sitemap.xmlpublic/_redirects:
/feed/ /feed.xml 301public/_headers:
/*
  X-Content-Type-Options: nosniff
  Referrer-Policy: strict-origin-when-cross-origin
  X-Frame-Options: DENY
/media/*
  Cache-Control: public, max-age=31536000, immutable
/_astro/*
  Cache-Control: public, max-age=31536000, immutable
Hash-named media and application assets can be cached immutably. HTML and Pagefind entry files need a different policy because their URLs remain stable while their contents change.
The headers above are a baseline. For a full CSP, generate inline-script hashes from the final HTML and accommodate Shiki’s token styles and Pagefind’s WebAssembly. Test the deployed policy rather than copying hashes from another site.
Search
The build indexes marked article bodies. Other pages stay outside the index. This UI uses Pagefind’s API and the site’s existing colors, shows up to 20 title links, and has loading and error states. Add excerpts and pagination as needed.
src/pages/search.astro:
---
import Base from '../layouts/Base.astro';
---
<Base title="Search" noindex>
  <h1>Search</h1>
  <form id="search"><label for="query">Search articles</label><input id="query" type="search" required /><button>Search</button></form>
  <p id="status" role="status"></p><ul id="results"></ul>
  <script is:inline type="module">
    const input = document.querySelector('#query'), results = document.querySelector('#results'), status = document.querySelector('#status');
    let sequence = 0;
    async function search() {
      const current = ++sequence, query = input.value.trim(); results.replaceChildren();
      if (!query) { status.textContent = ''; return; }
      status.textContent = 'Searching…';
      try {
        const pagefind = await import('/pagefind/pagefind.js');
        const found = await pagefind.search(query);
        const items = await Promise.all(found.results.slice(0, 20).map(item => item.data()));
        if (current !== sequence) return;
        status.textContent = `${found.results.length} results. Showing up to 20.`;
        for (const item of items) {
          const li = document.createElement('li'), a = document.createElement('a');
          a.href = item.url; a.textContent = item.meta.title; li.append(a); results.append(li);
        }
      } catch { if (current === sequence) status.textContent = 'Search could not load. Please try again.'; }
    }
    document.querySelector('#search').addEventListener('submit', event => {
      event.preventDefault(); history.replaceState(null, '', '#' + encodeURIComponent(input.value)); search();
    });
    input.value = decodeURIComponent(location.hash.slice(1));
    if (input.value) search();
  </script>
</Base>
Artifact checks
The verifier rejects unexpected files, symlinks, private CMS references, missing image assets and selected secret patterns. It also checks the supplied WordPress and Cloudflare credentials, including decoded gzip payloads.
Extend the asset allowlist deliberately for additional public files. Add a suitable secret scanner and known sensitive values without copying a credential store into the project. Compare imported IDs and paths against your expected inventory; the verifier alone cannot establish that every source article was imported.
scripts/verify.mjs:
import { readdir, readFile, lstat, access } from 'node:fs/promises';
import { gunzipSync } from 'node:zlib';
import * as cheerio from 'cheerio';
import path from 'node:path';
const forbidden = [/-----BEGIN (?:RSA |EC |OPENSSH )?PRIVATE KEY-----/, /(?:AKIA|ASIA)[A-Z0-9]{16}/];
const known = ['WP_PASSWORD', 'CLOUDFLARE_API_TOKEN'].map(name => process.env[name]).filter(value => value?.length >= 12);
const privateOrigin = new URL(process.env.WP_URL).origin;
let htmlCount = 0;
async function walk(directory) {
  for (const name of await readdir(directory)) {
    const file = path.join(directory, name), relative = path.relative('dist', file);
    const stat = await lstat(file);
    if (stat.isSymbolicLink()) throw Error(`Symlink: ${relative}`);
    if (name.startsWith('.') || /\.(?:env|sql|bak|map|php|pem|key)$/i.test(name)) throw Error(`Forbidden file: ${relative}`);
    if (stat.isDirectory()) { await walk(file); continue; }
    const allowed = /\.html$/.test(relative) || ['sitemap.xml', 'feed.xml', 'robots.txt', '_headers', '_redirects'].includes(relative) ||
      /^media\/[a-f0-9]{64}\.webp$/.test(relative) ||
      /^_astro\/[\w.-]+\.(?:css|js)$/.test(relative) ||
      /^pagefind\/[\w./-]+\.(?:js|css|wasm|pagefind|json|pf_fragment|pf_index|pf_meta)$/.test(relative);
    if (!allowed) throw Error(`Unexpected artifact: ${relative}`);
    const raw = await readFile(file);
    const decoded = raw[0] === 0x1f && raw[1] === 0x8b ? gunzipSync(raw, { maxOutputLength: 25 * 1024 * 1024 }) : raw;
    const content = decoded.toString('utf8');
    if (known.some(value => content.includes(value)) || forbidden.some(pattern => pattern.test(content))) throw Error(`Secret candidate: ${relative}`);
    if (content.includes(privateOrigin)) throw Error(`Private CMS reference: ${relative}`);
    if (relative.endsWith('.html')) {
      htmlCount++;
      const $ = cheerio.load(content);
      for (const element of $('img').toArray()) {
        const src = $(element).attr('src');
        if (!src?.startsWith('/media/')) throw Error(`Nonlocal image: ${relative}`);
        await access(path.join('dist', src.slice(1)));
      }
    }
  }
}
await walk('dist');
if (htmlCount < 3) throw Error('Unexpectedly empty build');
await access('dist/pagefind/pagefind.js');
console.log(`Artifact check passed: ${htmlCount} HTML files`);
Revision signal
Install this as wp-content/mu-plugins/static-revision.php, creating mu-plugins if needed. This reference signals broadly, including draft changes. That causes extra builds but never includes drafts in the public export. Restrict the hooks only after testing publication, unpublication, deletion, taxonomy, metadata and media changes.
Configure WordPress cron to run without public visits. The revision route requires an authenticated account with the read capability.
wordpress/static-revision.php:
<?php
/** Plugin Name: Private static publishing signal */
function example_static_changed() {
    update_option('example_static_revision', wp_generate_uuid4(), false);
}
// A broad signal is cheap; the starter also rebuilds after draft-only edits.
foreach (['save_post', 'deleted_post', 'set_object_terms', 'edited_term', 'delete_term', 'add_attachment', 'edit_attachment', 'delete_attachment', 'added_post_meta', 'updated_post_meta', 'deleted_post_meta'] as $hook) {
    add_action($hook, 'example_static_changed', 10, 0);
}
add_action('updated_option', function ($name) {
    if (in_array($name, ['blogname', 'blogdescription', 'permalink_structure', 'timezone_string'], true)) example_static_changed();
}, 10, 1);
add_action('rest_api_init', function () {
    register_rest_route('static-site/v1', '/revision', [
        'methods' => 'GET',
        'permission_callback' => function () { return current_user_can('read'); },
        'callback' => function () { return ['revision' => get_option('example_static_revision', 'initial')]; },
    ]);
});
Publisher and timer
The reference checks the revision before and after the full build and records success only after upload. A failed build leaves the successful state unchanged; the next timer run retries. Changes after the final check are handled on a later run. There is no cross-system transaction.
scripts/publish.mjs:
import { readFile, writeFile, rename, rm } from 'node:fs/promises';
import { spawnSync } from 'node:child_process';
const stateFile = '.state/deployed.json';
const cms = new URL(process.env.WP_URL);
if (cms.protocol !== 'https:') throw Error('Trusted HTTPS required');
async function revision() {
  const response = await fetch(new URL('wp-json/static-site/v1/revision', cms.href.replace(/\/?$/, '/')), {
    redirect: 'error', signal: AbortSignal.timeout(30000),
    headers: { Authorization: 'Basic ' + Buffer.from(`${process.env.WP_USER}:${process.env.WP_PASSWORD}`).toString('base64') }
  });
  if (!response.ok) throw Error(`Revision HTTP ${response.status}`);
  const data = await response.json();
  if (typeof data.revision !== 'string') throw Error('Invalid revision');
  return data.revision;
}
function run(command, args) {
  const result = spawnSync(command, args, { stdio: 'inherit', env: process.env });
  if (result.error || result.status !== 0) throw Error(`Failed: ${command}`);
}
const before = await revision();
let previous;
try { previous = JSON.parse(await readFile(stateFile, 'utf8')); }
catch (error) { if (error.code !== 'ENOENT') throw error; }
if (previous?.revision !== before || Date.now() - previous.at > 86400000) {
  await rm('public/media', { recursive: true, force: true });
  run('npm', ['run', 'build']);
  if (before !== await revision()) throw Error('CMS changed during build; retry next timer tick');
  run('./node_modules/.bin/wrangler', ['pages', 'deploy', 'dist', '--project-name', process.env.CF_PROJECT, '--branch', 'main', '--commit-dirty=true']);
  await writeFile(stateFile + '.tmp', JSON.stringify({ revision: before, at: Date.now() }), { mode: 0o600 });
  await rename(stateFile + '.tmp', stateFile);
}
Create a system account named static-builder, place the project at /opt/wordpress-static and create its .state directory. The reference account owns its working tree, which should be inaccessible to PHP. A stricter setup can keep source and dependencies root-owned while granting writes only to generated directories and tool caches.
Use the actual Node path from command -v node. systemd does not load an interactive version manager. Adjust memory limits to the image library and host.
/etc/systemd/system/wordpress-static.service:
[Unit]
Description=Build and publish the static blog
Wants=network-online.target
After=network-online.target

[Service]
Type=oneshot
User=static-builder
Group=static-builder
WorkingDirectory=/opt/wordpress-static
EnvironmentFile=/etc/wordpress-static.env
Environment=HOME=/opt/wordpress-static/.state
Environment=NODE_OPTIONS=--max-old-space-size=1024
ExecStart=/usr/bin/flock --nonblock /opt/wordpress-static/.state/publish.lock /usr/bin/node scripts/publish.mjs
UMask=0077
TimeoutStartSec=15min
NoNewPrivileges=true
PrivateTmp=true
ProtectHome=true
ProtectSystem=full
MemoryMax=1700M
Nice=10/etc/systemd/system/wordpress-static.timer:
[Unit]
Description=Check WordPress for publication changes

[Timer]
OnBootSec=90s
OnUnitInactiveSec=60s
AccuracySec=5s

[Install]
WantedBy=timers.target
First deployment
Create a Pages Direct Upload project from an authenticated administrative shell:
./node_modules/.bin/wrangler pages project create my-static-blog \
  --production-branch main
Give the runtime token Pages Write permission for the intended account. It does not need DNS or WAF administration permissions.
Astro’s current Cloudflare guidance points new projects toward Workers. This setup uses Pages for static delivery, as covered by the Pages Astro guide. It does not require a runtime adapter or Functions.
Run one complete deployment before enabling the timer:
sudo systemctl daemon-reload
sudo systemctl start wordpress-static.service
sudo journalctl -u wordpress-static.service -n 60 --no-pager
Check the temporary deployment hostname. Canonicals should already use the intended production domain. Keep preview hosts out of search with host-specific response headers or access controls. A global noindex on the production artifact would also hide the public site.
Acceptance checks and cutover
The reference was built against a synthetic WordPress fixture. Routes, sanitization, responsive media, Shiki and article-only indexing passed. Deliberately added environment files and known credentials were rejected. Browser checks covered mobile light/dark appearance, stored overrides, exact clipboard text, the checkmark and search. The example’s full WordPress service and Cloudflare deployment were not run against a second live installation.
For your own migration:
- Compare expected source IDs and paths with the import and output. Check titles, dates, SEO fields, canonicals, indexing decisions, feed and sitemap. Confirm protected posts and drafts are absent from both pages and search data.
- Decode body images, covers and generated sizes. Compare image identities, accounting for galleries whose order changes. Repair or explicitly resolve every missing source.
- Compare code text, indentation and copied content. Repeat against the CDN-served site to catch transformations after deployment.
- Test narrow phones and desktop widths in both themes. Check overflow, token contrast, touch targets, OS defaults, stored choices and blocked storage.
- Test successful search, no results and network failures. Inspect network requests for CMS calls, external assets and scripts you did not intend to ship.
- Run mobile Lighthouse on the homepage, archives and representative long articles. Recheck the production custom domain, not only a local preview.
- Test editing, publishing, changing media, unpublishing and deletion. Simulate a failed build and verify that the previous deployment remains available and successful state does not advance.
npm run preview -- --port 4321 serves the built output locally. An Astro development server does not produce the Pagefind index.
Add the production domain through the Pages custom-domain flow and follow its DNS instructions. Verify TLS, redirects and response headers. Close the old public reverse proxy, tunnel or forwarding route and restrict origin access to private clients. From outside the network, confirm that the old origin and public WordPress login, admin, REST and PHP paths cannot reach WordPress. From inside, verify the editor and importer still work.
Then enable the timer:
sudo systemctl enable --now wordpress-static.timer
sudo systemctl list-timers wordpress-static.timer
Verify the custom domain after automatic publication, including removed pages and the search index. A successful upload does not prove that cached responses have disappeared.
To roll back, disable the timer and restore a known-good static deployment, then verify the domain. Reopening public WordPress restores the old exposure and should be a separate deliberate decision.